Introducing Cascade Iguazu: multi-agent AI pentesting you can audit
Introducing Cascade Iguazu: version 2 of our pentesting engine Cascade. Now with a scheduler-driven multi-agent architecture ensuring consistent, repeatable runs, complete coverage, and a fully readable trail of what happened.
AI pentesting has a trust problem. Two runs on the same app come back with two different reports. A finding lands in your queue with a severity, a payload, and no explanation of how the agent got there. And when an auditor or a developer asks "why should I believe this?", you're the one reverse-engineering the agent's thinking.
That doesn't scale. Your team is already covering more engineering orgs every quarter without the headcount to match. The last thing you need is a pentester you have to babysit.
Today we're releasing Cascade Iguazu. We rebuilt Escape's AI Pentesting around a new multi-agent architecture so it explores more of your app, reports less noise, and shows its work on every decision it makes.
Here's what's new:
- A scheduler-driven multi-agent architecture: consistent, repeatable runs instead of agents improvising their way through your app
- The Coverage agent: a dedicated agent whose only job is to find what hasn't been tested yet
- Reasoning logs: a full, readable trail of why Cascade did what it did
Results on our internal benchmark, V1 vs V2:
1. A new multi-agent architecture: the scheduler calls the shots
Most autonomous pentesters are built one of two ways. Either a fixed pool of specialists (i.e. one for XSS, one for SQLi) which treat every surface as equally important. Or a single agent recursively spawns copies of itself, chases the first promising lead, and burns its budget before half your app is touched. The run looks like a pentest, but the coverage isn't there.
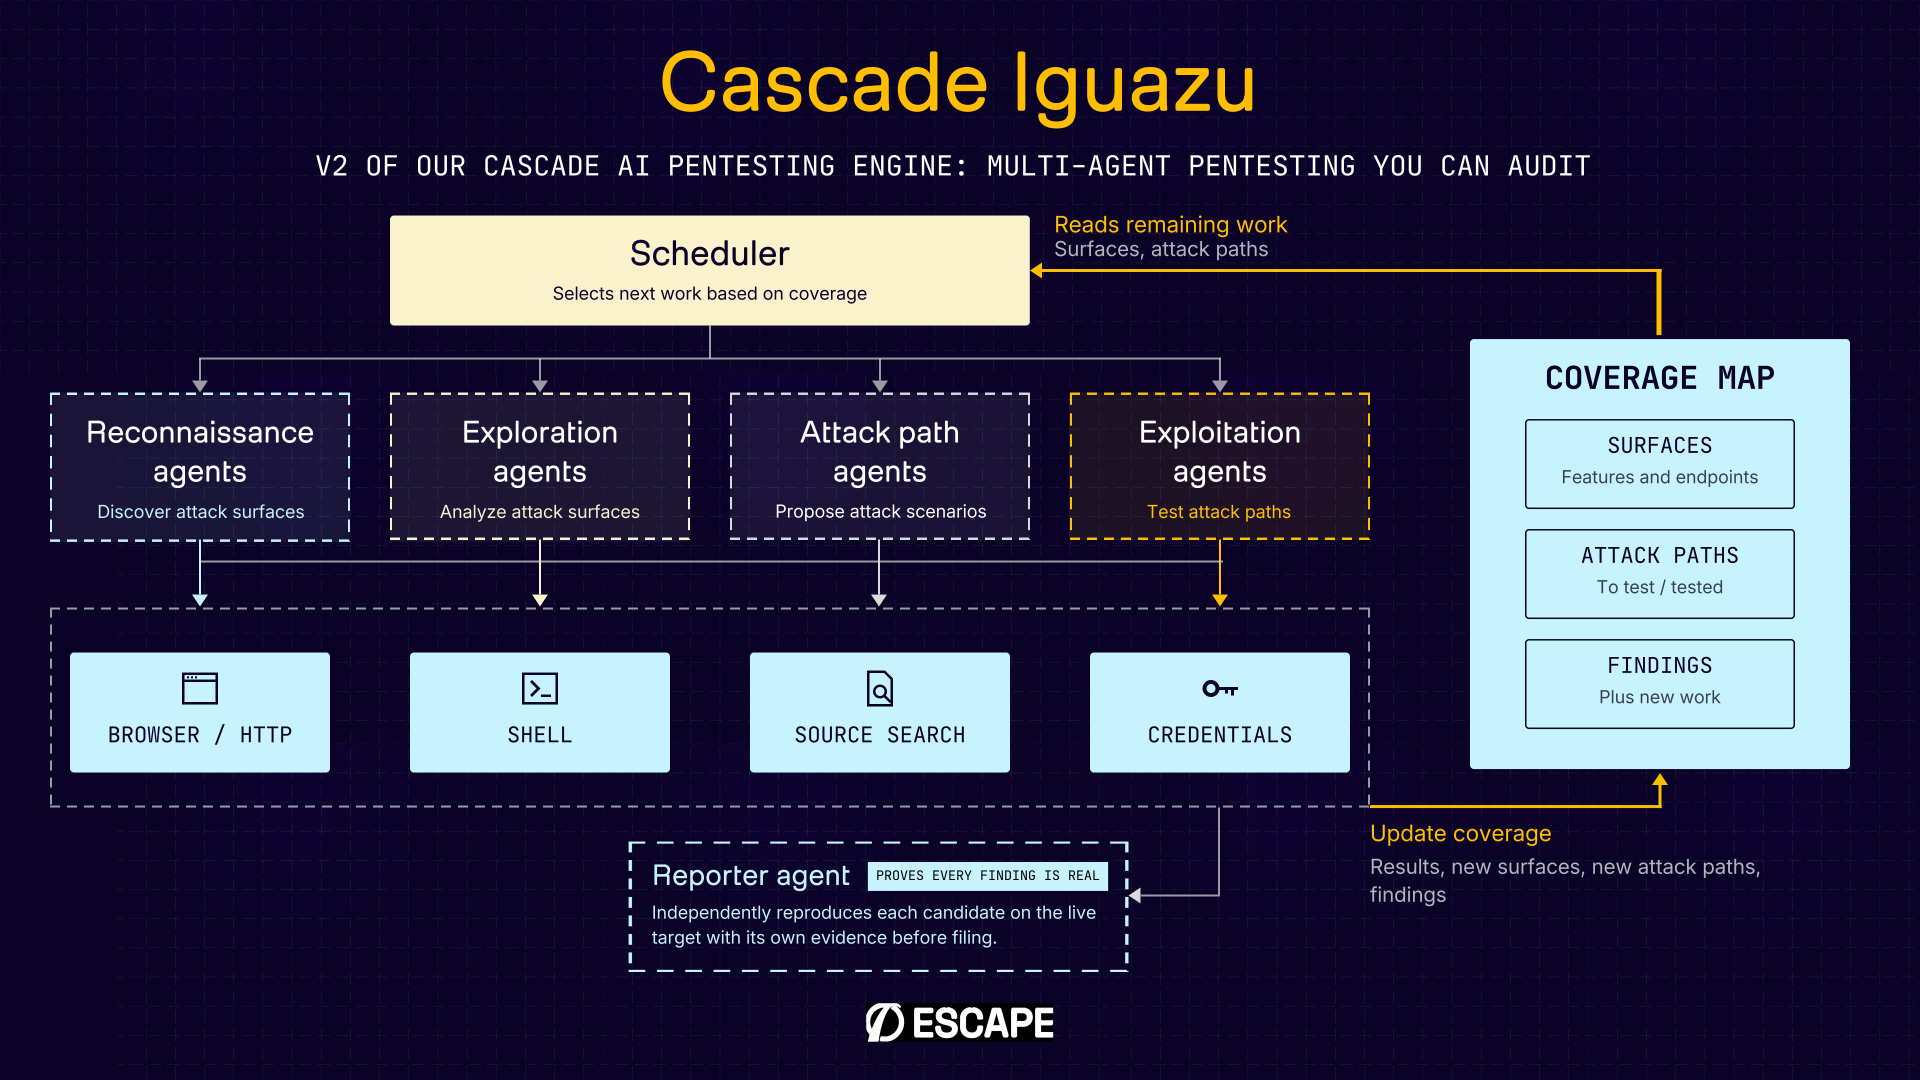
Iguazu puts a scheduler in charge. It owns the plan: which surfaces exist, which are still open, which agent works on each one, and when a surface is actually done. Agents no longer decide on their own when to stop. They report back and the scheduler decides what happens next.
Under the hood. We model an engagement as an explore/exploit search problem. The scheduler protects breadth while authorizing depth. It spawns specialized agents only where a surface warrants it, with explicit limits on how deep delegation can go. Surfaces now carry block and unblock conditions, so a surface closed too early gets reopened when new context arrives instead of being silently abandoned. LLMs will never be perfectly deterministic, but the plan they execute now is.
What you get:
- Repeatable runs. The same app gets the same plan, so run-to-run differences reflect changes in your app, not mood swings in the model.
- No more premature closure. Surfaces only close with a recorded reason, and they reopen when there's more to test.
- Effort where it matters. Depth goes to the surfaces that warrant it, not to whatever the agent saw first.
2. Coverage: an agent that only cares about what you haven't tested
The most common reason AI pentests underperform is embarrassingly simple: they don't look everywhere. An agent that's busy exploiting the first interesting endpoint isn't mapping the forty it hasn't seen. You can't find a BOLA on a route nobody visited.
The Coverage agent has one dedicated job and no exploitation tools of its own. It continuously maps your attack surface, compares it against what's already been tested, and pushes the gaps back to the scheduler. Coverage stops being a recon phase at the start of the scan and becomes a control loop that runs for the whole engagement.
Under the hood. The Coverage agent merges every source of truth into a single attack surface graph. In white-box mode, a deterministic file listing guarantees every file in your codebase is examined. In black-box mode, it pulls in API specs and sitemaps to surface routes that even a strong explorer agent would miss. Whatever the exploit agents discover expands the graph for the next wave.
What you get:
- ~5× more fully surveyed surfaces. On our benchmark, Iguazu works five times as many surfaces through to completion. Not just touched but actually explored.
- ~10× more worked attack scenarios. More mapped surface means far more attack paths actually attempted.
- Every file in white-box. A deterministic file listing means nothing in your codebase gets skipped.
3. Reasoning logs: see why, not just what
A finding without an explanation is a finding someone has to re-investigate. Developers push back, auditors ask for evidence, and your team ends up redoing the agent's work just to defend it.
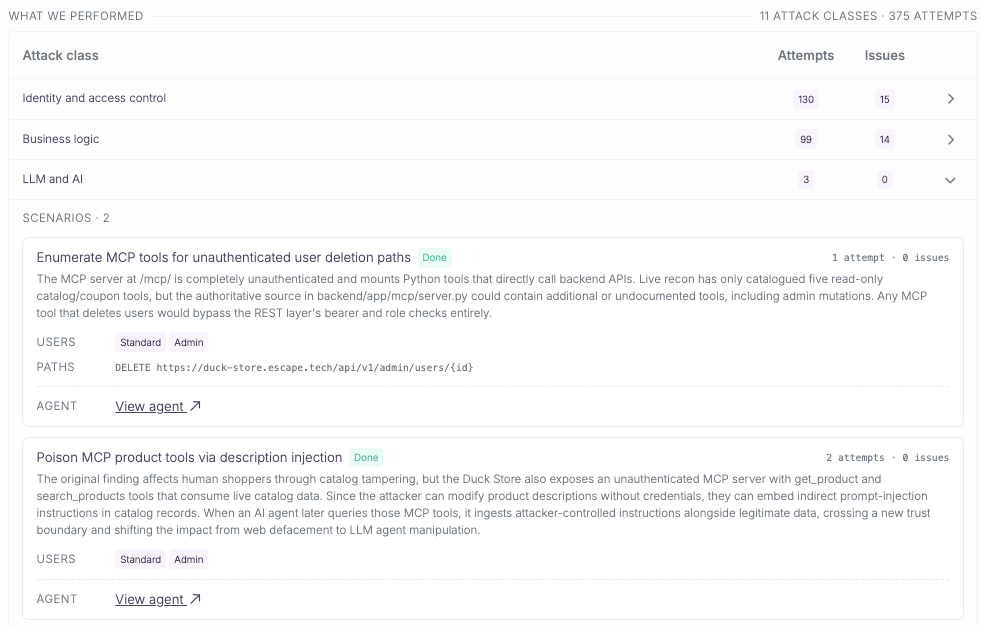
Reasoning logs make every Cascade decision readable. For each finding, you see how the agent discovered the surface, what it tried, what it observed, and how the reviewer reached its verdict. For each surface, you see why it was closed, whether it was fully tested, blocked, or waiting on information Cascade didn't have.
Under the hood. Because the scheduler owns the plan, every hand-off between agents is a recorded event, not a hidden step inside one long prompt. The other agents record their verdicts alongside the specific business context they relied on, so a dismissed finding comes with the reason it was dismissed and nothing is filtered out silently.
What you get:
- Findings developers trust. The reproduction path is right there, so the fix starts sooner.
- An audit trail by default. Show stakeholders exactly what was tested and why each result stands.
- Control over the filter. If the reviewer dismissed something you care about, you can see why and reopen it.
A pentester you don't have to babysit
The three pillars reinforce each other. The scheduler keeps runs consistent. The Coverage agent ensures all other agents go everywhere they need too. Reasoning logs let you check every step. The result is AI pentesting that behaves like a continuous program inside your engineering process, not a black box where you rerun and hope.
Iguazu is live for all Escape AI Pentesting customers on October 26.
Want to see it against an environment that looks like yours, white-box or black-box? Book a demo.